Showing posts with label outside database. Show all posts

2/01/2015

esProc External Memory Computing: Basic Usages of the Cursor

esProc supports importing big data in batches with the cursor, which is the usual method used in big data computing. Usages of cursors, including external file cursor, database cursor and in-memory record sequence cursor, are basically the same. This article will take the external file cursor as the example to explain basic usages of the cursor in esProc.

1. Data fetching


When a cursor is created, its data can be fetched by cs.fecth() function. Different from the way data of an ordinary table are imported, data in the cursor are fetched by specifying the number of rows to be returned, or one or more conditions on which data will be fetched, rather than being fetched all at once. For example:
A2 creates an external file cursor. A3 fetches the first 1,000 rows from it, as shown below:
With fetch function, each batch of data fetched from the cursor will be returned as a table sequence. A4 calls cs.close() function to close the cursor. When a cursor is closed, data cannot be fetched from it. That is why the result of A5 is null:
When the cursor has accomplished its mission and is not needed any more, it ought to be closed through calling cs.close() function to release the memory.

Besides fetching data from the file or the database result set with the cursor, cs.skip() function can be used to skip the specified number of rows in the cursor. For example:
A2 creates the cursor and A3 skips 45,000 rows. Then A4 fetches data from the cursor as follows:
As can be seen from the transaction ID, the data fetching begins from the 45001th row. Notice that the fetch function in A4 doesn’t specify the number of rows to be returned. In this case, all the rest of the data in the cursor will be fetched. Once data in the cursor are completely fetched, the cursor closes automatically, without the necessity of calling cs.close() function.

So A5 fetches nothing from A2’s cursor:
In fact, both cs.skip() function and cs.fecth() function will only traverse the cursor data once from front to back. When the data fetching is over or cs.close() function is executed, the cursor becomes useless.

Another type of fetching data from the cursor using cs.fecth() function is cs.fetch(;x), which specifies the condition on which data fetching will continue interruptedly until the value of expression x changes. For example:
A2 creates the cursor. A3 fetches data from it until the value of Date changes. The fetched data are as follows:
It can be seen that A3 fetches all data whose Date value is 2013-01-01. When A4 goes on with fetching data from A2’s cursor, it will begin from the date 2013-01-02:
Note that we cannot specify both the number of rows to be returned and the condition for data fetching at the same time; otherwise only the former is valid. Besides, since not all the data in A2’s cursor have been fetched, the cursor needs to be closed in A5 after doing its job.

Similarly, we can also specify condition for cs.skip() function to skip certain records. For example:
A2 creates the cursor. A3, A4 and A5 respectively skip records of one day. Then A6 will fetch data from the cursor from the fourth day:
Similarly, if not all the data have been fetched from the cursor, call cs.close() function in A7 to close the cursor.

2. Cursor loop

When fetching data from the cursor, use for statement to process the rows returned from the cursor by loop. For example:
A2 creates the cursor. By loop, A3 processes 1,000 records returned by the cursor each time. After all records are traversed, the cursor closes automatically. In A3’s code block, based on the table sequence returned by the cursor each time, the code computes the total sales amount of the salesperson whose ID number is 1 and stores the result in B2. The value is shown as follows:
Sometimes not all data need to be traversed during the cursor loop. For example:
A2 creates the cursor and A3 executes cursor loop, fetching 1,000 records each time. In A3’s code block, according to the batches of data fetched from the cursor, the code selects the sale records of the salesperson whose ID number is 1 and stores them in B2. Exit the loop after the first 5 records are fetched. At this point the result seen in B2 is as follows:
One point worthy of special note: When the computation is over and the loop is terminated by break function, there are data still remaining in the cursor. Different from the previous example, in this case the cursor won’t close automatically, thus close function is called in A6 to close it and release the memory.

Similar to cs.fecth() and cs.skip(), the condition can be specified for the cursor loop, so that the data fetching will stop as soon as the value of the conditional expression changes. For example:
With the condition, A3 fetches the sales data of one day each time, computes the number of transactions and the total sales amount in this day in its code block and stores the results in B2’s table sequence. After the code is executed, B2’s result table sequence is as follows:

3. Computation with the cursor

Besides data fetching, esProc offers the use of cursor in performing common forms of data computing by directly using certain functions. The following example is to select data from the cursor according to the condition:
B1 creates the external file cursor and A2 selects the sales data of the salesperson whose ID number is 1 from B1’s cursor. A2’s result is as follows:
It can be seen that, different from the table sequence or the record sequence, the select function used with the cursor returns the cursor as the result. Actually A2 hasn’t really got data from the cursor. It is in B2 where cs.fecth() function is being executed that the eligible data are fetched from B1’s cursor according to the condition. Result of B2 is as follows:
No number of rows to be returned or the condition for data fetching is specified for cs.fecth() function used in B2. All data, or all the sales data of the salesperson, in A2’s cursor will be returned. After data of the cursor in A2 have all been fetched out, the cursor will close automatically. Since the cursor in A2 is generated from the one in B1, the data query is in fact executed by traversing data of the cursor in B1 and the completion of fetching data from the cursor in A2 means the same thing to the cursor in B1, which will close at the same time. Therefore the effort of A3 and B3 trying to fetch data from the cursors in either A2 or B1 will definitely fail.

The cursor can also be used to create new records, or append new fields. For example:
B1 creates a file cursor using some of the fields of the external file employee.txt. In A2, the employees’ full names are generated by joining NAME field and SURNAME field in B1’s cursor together. B2 computes each employee’s age according to the BIRTHDAY field in B1’s cursor and insert the results to Age field. Similar to cs.select(), both cs.new() and cs.derive() return cursor as the result, rather than returning data directly. When executed, A2 and B2 have the following results:
A3 fetches the first 100 rows from A2’s cursor:
Generating data with cs.new() function means executing new statement on every record.
B3 fetches the first 100 rows from B2’s cursor:
Generating data with cs.derive() function means appending computed columns into the returned table sequence.

It can be seen that B3’s data begin not from the first employee, but from the 101th one. That’s because fetching data from cursors in A2 and B2 is, in reality, fetching data from the cursor in B1 and cursor data will be traversed only once from front to back. After A3 is executed, the first 100 rows of data in B1’s cursor have been traversed. So B3 can only go on with the traversal in order in the execution of cs.fecth() function by beginning with the 101th employee.

Because data haven’t been all fetched out, the cursors need to be closed using cs.close() function. As A4 closes the cursor in A2, the cursor in B1 is also closed simultaneously, for the former is generated by the latter. This affects the cursor in B2, from which B4 is trying to fetch data but to no avail.

In practical use, we ought to avoid using the same cursor to generate multiple ones as possibly as we can; the same problem as the one with B3 in fetching data, or as another one that cursors will be unavailable when the source cursor closes, will arise otherwise.

What’s more, cs.run() can be used to modify values of a certain field of cursor data. For example:
B2 replaces names of the states in the returned data by their abbreviations and still returns the cursor as the result:
A3 fetches the first 100 rows as follows:
Similar to a table sequence, the cursor allows the conversion of a certain field of its data into the corresponding records in another table sequence by using cs.switch() function. For example:
B2 uses cs.switch() to switch certain data of the cursor. Its result is also a cursor:
The data A3 fetches are as follows:
It can be seen that, in the return result, STATE field has been converted into the corresponding state records.

cs.switch() can convert more than one field of the cursor. For example:
B3 switches records of several fields of the cursor to the corresponding ones in another table sequence. A4 fetches the first 100 records:
In the article – RelatedComputing in esProc – Primary Keys and Index Function, we explained the usage of switch in the ordinary table sequence, which is similar to that of cs.switch() in external memory computing. Both functions will create corresponding index table for certain field(s) of the dimension table in order to increase efficiency. It is more important to adopt this processing method while using the cursor because the data under processing are usually big. 

1/29/2015

esProc External Memory Computing: Concept of Cursor

The concept of cursor is very important for the database. With the cursor, data can be manipulated more flexibly and returned from the data table by rows. esProc supports many types of cursor, like database cursor, file cursor and in-memory record sequence cursor, to satisfy various needs in data fetching and processing. In this article, we’ll introduce what the cursor used in esProc is and its three types.

1. What is cursor

Using the cursor in the database enables returning the result in batches, instead of trying to retrieve all of it into the memory at a time. The cursor is like a pointer, it fetches one row of data each time from the result set by moving its own position. This mechanism of retrieving data by rows is usually used to process big data table, which cannot be entirely loaded into the limited memory.

Compared with directly returning all result, the database cursor is flexible enough to avoid the memory overflow but its speed of processing is not very fast.

There are some differences, however, between esProc cursor and database cursor:
1)  esProc cursor is only used to get data without modifying the result set.
2)  Data are traversed only once from front to back during fetching data from the esProc cursor, which is similar to the setting of TYPE_FORWARD_ONLY in JDBC.
3)   esProc cursor can be created based on either the database or the data file, or the in-memory record sequence.
Different types of esProc cursors have similar usages and we can mix and match them to suit the requirements.

2. Database cursor


With db.cursor(sql) function, data returned from the database can be converted into the cursor. For example: 

A1 creates a database cursor. A2 fetches the first 100 records from it, as shown below:

Data fetched from the cursor with cs.fetch() will be returned as a table sequence.

A3 will follow on to fetch another 100 records in order, for esProc allows only a single traversal of cursor data from front to back:

As can be seen from EID field, A3 fetches the records from the 101th employee. In this example, cs.fetch() is used merely to fetch data from the cursor. For more usages of the esProc cursor, please refer to esProc External Memory Computing: Basic Usages of the Cursor.

If the data in the cursor haven’t been all fetched out when data fetching is over, use cs.close() to close the cursor. It is very important to close the cursor, particularly the database cursor, timely. Because the database cursor gets data from the database, the existence of it means the connection to the database will remain, causing unnecessary memory usage and even the overrun of cursors allowed to be created by the database.

Similar to the use of db.query() function in data query, the parameter is allowed in creating a database cursor. For example:

In SQL statements, parameters can be represented by the question mark (?). They are entered in a certain order after it and separated by the comma. A1’s cursor will return data of female employees whose EID is greater than 100. A2 returns all data of A1’s cursor, as shown below:

The number of rows of data to be returned is not specified for the cs.fetch() function used in A2, thus all data in the cursor will be returned. When data in a cursor have all been fetched out, it will close automatically with no need of calling cs.close().

3. External file cursor

In practice, particularly big data processing, data are often generated from the file rather than the database. Given this, esProc provides the function of creating the external file cursor for data fetching based on the structured file. The following text file PersonnelInfo.txt holds the personnel information:

In the file, each row holds a record and columns are separated by tabs. The external file cursor can be created according to the file for data fetching. For example:

A2 creates a cursor based on the external file and uses @t option to make the file’s first row the column names of the result set. A3 skips the first 50,000 rows and then A4 fetches 100 rows from A2’s cursor, as shown below:

As the database cursor, data are fetched from the external file cursor through a single one-way traversal. After A3 skips certain rows using cs.skip(), the data fetching in A4 will begin from the 50,001th row.

While creating a cursor based on a certain file, it is not necessary to use all its fields. We can specify fields to create the cursor, for example:

The code in the above cellset is almost the same as that the previous one, except that A2 creates the external file cursor using specified fields.
Note: It’s only after field names are imported using @t option that they can be used to specify fields. Without the option, fields can only be specified directly by their positions, like =A1.cursor(#1, #2, #6, #3).

About the external file cursor, we’ll make a deeper explanation in esProc External Memory Computing: Text Files.

4. In-memory record sequence cursor

In esProc, the result table sequence or record sequence can be converted into the cursor to be used with other types of cursor. For example:

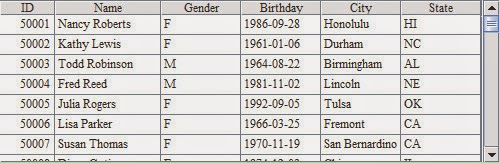
The following is data of the states A1 selects:

A2 creates a cursor using the table sequence:

Generally the in-memory record sequence is converted into the cursor to perform some operations based on the cursor, like merging and joining the cursor data. For details in this respect, please refer to esProc External Memory Computing: Merge and Join Cursor Data.

Besides, the cursor can be created based on the result table sequence or record sequence got in another cellset file. Take cellset file createTable.dfx as an example:

The result of the cellset file returned by the result statement can be converted into a cursor, as shown below:

A2 fetches the first 100 rows from the A1’s cursor:
This is only a simple conversion of a result table sequence got in another cellset file into the in-memory record sequence cursor, which is a kind of cross-cellset cursor in this case. More usages of the cross-cellset cursor will be illustrated in the esProc External Memory Computing: Cross-cellset Cursor. 

1/28/2015

esProc External Memory Computing: Text Files

Sources of data used for analysis usually fall into two categories: the database source and the file source. Compared with the database data, the file data are simple to deploy and publish. The problem is that, since the file data generally need to be used as a whole and thus need to be loaded into the memory all at once, they are not so easy to handle when being big. esProc offers solution to this problem by fetching them with the cursor. This makes the use of file data more convenient.

This article will explore how to manipulate file data in esProc through the case of text data - the most common external file data.

1. Basic usage

file function and import function can be used to read data from text files. The text file employee.txt holds information of 500 employees, as shown below:
EID       NAME       SURNAME        GENDER  STATE        BIRTHDAY        HIREDATE         DEPT         SALARY
1  Rebecca   Moore      F       California 1974-11-20       2005-03-11       R&D          7000
2  Ashley      Wilson      F       New York 1980-07-19       2008-03-16       Finance    11000
3  Rachel      Johnson   F       New Mexico     1970-12-17       2010-12-01       Sales         9000
4  Emily         Smith        F       Texas        1985-03-07       2006-08-15       HR    7000
5  Ashley      Smith        F       Texas        1975-05-13       2004-07-30       R&D          16000
6  Matthew Johnson   M     California 1984-07-07       2005-07-07       Sales         11000
7  Alexis        Smith        F       Illinois       1972-08-16       2002-08-16       Sales         9000
8  Megan     Wilson      F       California 1979-04-19       2004-04-19       Marketing        11000
9  Victoria    Davis        F       Texas        1983-12-07       2009-12-07       HR    3000
…

esProc sets rules for the format of the text data used in the data table: Records must be separated by the carriage return and fields should be separated by the tab. Text data can be imported using simple code: 
In esProc, import function is used to import the file data as the table sequence. In the above cellset, A1 creates a file object. If the path hasn’t been specified in the file name, it can be found in the main path on the settings page. Click on Tool>Options on the menu bar to view or set the main path on the Environment page of Option window:
A2 imports the file as a table sequence. The use of @t option in the import function will import the text file’s first row as the column names. For a clearer comparison, the option is omitted in A3’s data import. After the code is executed, A2’s table sequence is as follows:
Not all files necessarily use tab as the field separator. The CSV file, for instance, uses commas. We can specify a separator for a file when using import. Thus A2’s code can be modified as =A1 .import@t(;",").

A3 generates a table sequence as follows:
It can be seen that, when @t option is omitted, the table sequence’s field names will be automatically generated and named _1,_2,_3 according to their positions respectively.

When the text data are being imported, their data type will be automatically parsed according to the data type of the first row. As the first row of employee.txt holds field names, all data of A3’s fields will be parsed into strings, like column _1 and column _9 in the result above, which are left-justified. While the type of data in A2’s EID field and SALARY field is integer, and the data are right-justified.

We can import only some of the fields to generate a table sequence. For example:
The use of @t option in A2 means that we can directly use names to specify fields to be imported. Result of A2 is as follows:
Without @t option, A3 specifies the fields with their serial numbers in the format #i. The result table sequence is as follows:
As mentioned above, during text data import, data type will be automatically parsed according to that of the first row. If a particular data type is wanted, it can be defined for the specified fields to be imported. For example:
The following is the set of settings used in esProc to specify the data type for the field:
To learn more about the data type, please refer to esProc Getting Started: Basic Data Types.

A2 specifies data types for EID field, BIRTHDAY field and SALARY field – string, date and integer respectively. When executed, A2’s result table sequence is as follows:
A3 specifies the same data types for the fields as in A2. The result table sequence is as follows:
It can be seen that if certain data of a field cannot be parsed into the specified data type, they will be parsed automatically, like those of the title row, which have been automatically parsed into strings.

About the subsequent computations after data are imported, please see the article esProcProgram: Operations on Table Sequences and Record Sequences.

In esProc, not only text data can be imported as a table sequence, in-memory data can also be exported to a text file. The to-be-exported data are usually those of the table sequence or the record sequence, or sometimes, members of the sequence. export function is used to export data to the file. For example:
A1 creates a file object, employee1.txt, to save data. But at this point the file data are still stored in the report’s main path.

A2 creates a table sequence and inserts two records into it:
A3 exports the data of the table sequence to file employee1.txt:
We can use @t option to export the column names. And we can specify certain fields to be exported. By modifying A3’s code into >A1.export@t(A2,NAME), the exported data in employee1.txt are as follows:
As in import, tab is used as the default field separator in export. Of course we can also specify the field separator used in the function.

2. Batch processing of big data

When a file holds big data, to load it all together to the memory may cause the memory overflow. In this case, only some of the data ought to be imported each time. import function can be used to realize this by specifying the beginning byte and the ending byte. For example:
The text file PersonnelInfo.txt holds the personnel information. A2 specifies the range of data import - from the 10,000th byte to the 20,000th byte. Since only the complete record has meaning in the result table sequence, esProc will adjust the positions of beginning byte and ending byte to ensure they are respectively in a record’s starting point and another record’s ending point. The imported data in A2 are as follows:
As we can see, @t option can still be used to import field names while importing data through specifying the range.

A3 continues to import data from the 20,000th byte to 30,000th byte. Result is as follows:
The two results show that the personnel information in A2 and A3 is continuous. esProc specifies the range for data import in a uniform way to ensure the continuity, integrity and uniqueness of the imported data. A text file with big data can thus be imported and processed in batches to avoid the memory overflow.

In addition to directly specifying beginning and ending positions for data import, @z option can be used in import to import data segmentally. For example:
A2 and A3 use both @t and @z in the import function to import column names as well as the data in segments. That means we can use multiple options simultaneously in a function. A2 divides data into 500 segments and imports the 100th segment. Its result is as follows:
A3 continues to import the 101th segment. Its result is as follows:
It can be seen that, during the batch import, esProc is also able to ensure that complete records are imported by setting appropriate positions for beginning and ending points, and at the same time, the continuity, integrity and uniqueness of the imported data.

Note: With import function in which the file is imported in batches by specifying the beginning and ending bytes or dividing it into segments, the number of imported rows of data is different for each batch because of the variation of the number of bytes each record holds. This also explains why a specified row of data cannot be got directly. To locate the record in a specified positon, all records before this position need to be traversed. This is not efficient at all. Yet, the external file cursor can be used to access the target record precisely, which will be explained in the next section.

The export of big data to a text file can also be hindered by the limited memory. Because data cannot be loaded into the memory all at once, they cannot be exported to a certain file by simply using export. But similarly, they can be exported in batches. Use @a option in export function to append data to the existing data at each batch of data export. For example:
The loop in A2 imports data from PersonnelInfo.txt in 500 segments and specifies certain fields to be written to a new file PersonnelInfo1.txt. @at options are used in export to export both column names and data by appending each batch export to the previous data. When the code is executed, PersonnelInfo1.txt gets data as follows:
But without @a option, the existing data in the file will be removed at each time of export.

3. Access big text files with the cursor

A more convenient tool to process text files containing big data is the cursor. Cursor functions can be called conveniently after the external file cursor is generated based on the text file. For example:
A2 creates a file cursor using cursor function, in which @t option is used to make the file’s first row the column names. A3 skips the first 10,000 rows. A4 and A5 respectively fetch 1,000 rows from A2’s cursor:
Data can be fetched conveniently and quickly by their position from the cursor. As with f.import() in section one, fields can be specified for creating a cursor and the data type of a certain field can be defined with f.cursor().

With the external file cursor, we are able to handle various operations easily. About its usages, please refer to esProc External Memory Computing: Basic Usages of the Cursor and other articles on esProc external memory computing.

Also through the cursor, data can be exported to a file. For example:
A2 creates a database cursor. A3 gets the expected result by computing the cursor data and then export it to the file. After the code is executed, employee2.txt holds data as follows:
Exporting data through the cursor is convenient and the code is concise. To retain the existing data during the data export, use @a option to append each batch export to the previous data.

Besides the text file, esProc also supports the binary file. The latter takes up less memory space and makes the computation more efficient. For its usages, please see article esProc External Memory Computing: BinaryFiles.